# SeedAudio 1.5
> SeedAudio 1.5 is the next-generation AI audio model for dialogue, music, ambience, and sound effects.
## Overview
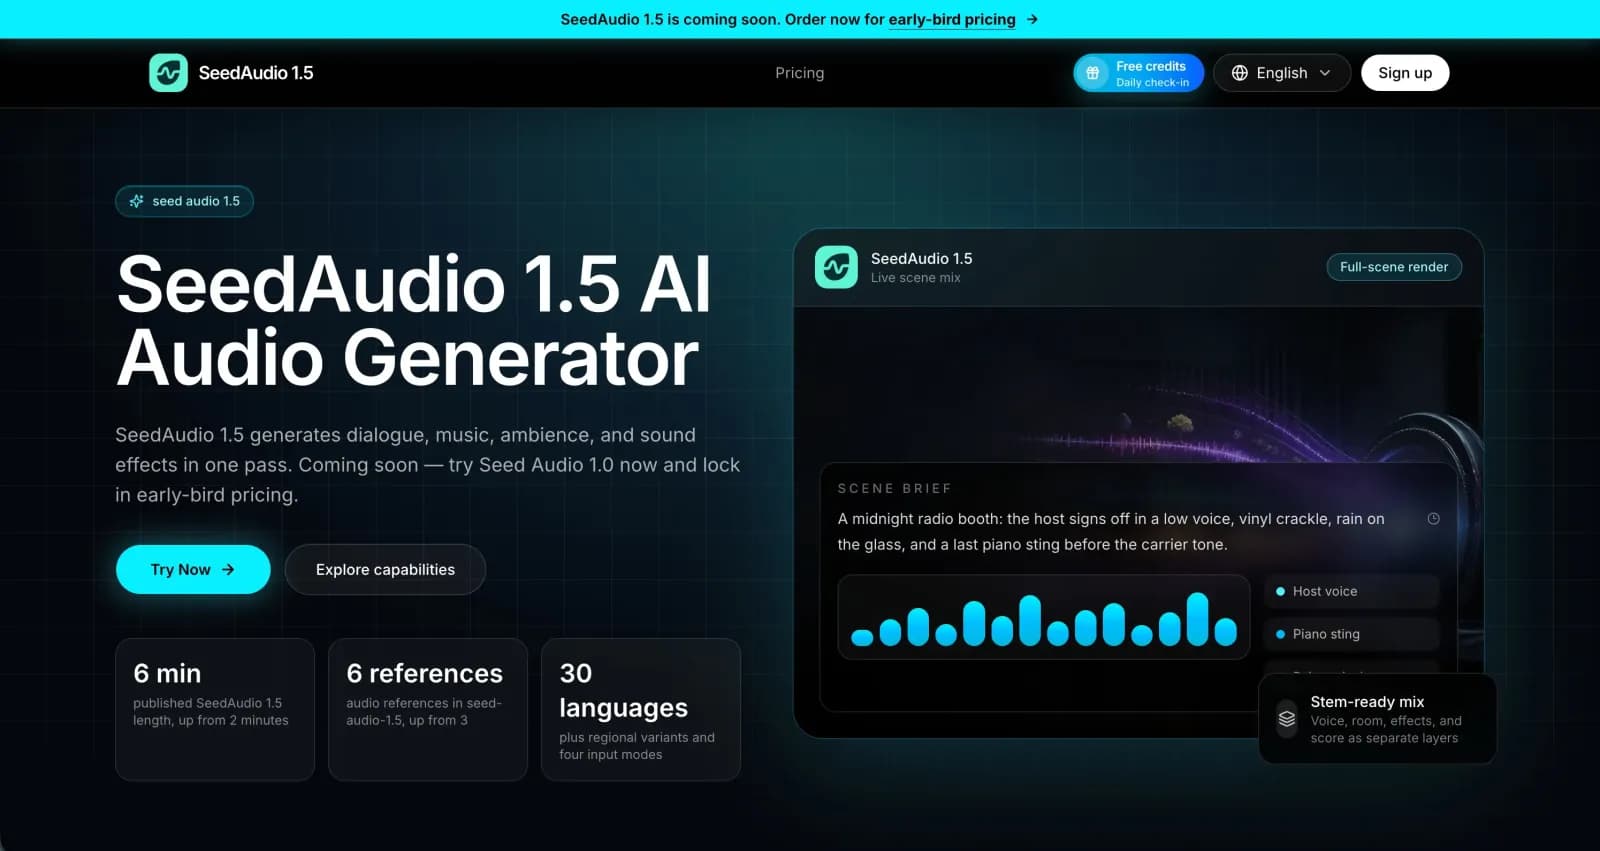
- SeedAudio 1.5 (also written seed audio 1.5 and seed-audio-1.5) is coming soon. Published capabilities include dialogue, music, ambience, and sound effects in one pass, up to six minutes, six audio references, 30 languages, four input modes, video-aware dubbing, timestamps, and separate tracks.
- The homepage generator currently runs Seed Audio 1.0. Orders placed now lock in early-bird pricing for SeedAudio 1.5.
- Signed-in users can use the web generator when provider configuration and credits are available; pricing is credit-based and plan prices are unchanged.
## Primary Pages
- [Homepage](https://seedaudio15.org/): Main landing page for capabilities, the web generator, use cases, FAQs, and pricing access.
- [Chinese homepage](https://seedaudio15.org/zh): Chinese version of the homepage for readers who prefer Simplified Chinese.
- [Join updates](https://seedaudio15.org/sign-up): Sign-up page for creating an account before generating audio or buying credits.
- [Pricing](https://seedaudio15.org/pricing): Subscription and one-time credit pack options for AI audio generation.
## Key Sections
- [Version guide](https://seedaudio15.org/#versions): Side-by-side comparison of the upcoming SeedAudio 1.5 specifications and the live Seed Audio 1.0 generator.
- [Capabilities](https://seedaudio15.org/#capabilities): Summary of Seed Audio 1.0 as a sound-scene model beyond ordinary text-to-speech.
- [Use cases](https://seedaudio15.org/#use-cases): Creative uses for short films, marketing creatives, games, XR prototypes, podcasts, and learning content.
- [FAQs](https://seedaudio15.org/#faq): Answers about inputs, availability, generation length, prompt examples, commercial use, and whether the page includes a live generator.
## Machine-Readable Resources
- [llms.txt](https://seedaudio15.org/llms.txt): Concise machine-readable guide to SeedAudio 1.5 for LLMs and AI assistants.
- [llms-full.txt](https://seedaudio15.org/llms-full.txt): Expanded machine-readable guide with model context, prompt guidance, and use-case notes.
## Core Model Context
- Seed Audio 1.0 is best described as an AI audio generation model, not only a text-to-speech model.
- A strong prompt should define characters, setting, emotion, pacing, spoken dialogue, music mood, ambience, and specific sound events.
- The model direction emphasizes complete sound scenes: multi-speaker dialogue, emotional tone, accents, ambience beds, BGM, and sound effects.
- Multimodal context can be useful for steering characters, mood, rhythm, ambience, music, and effects.
- Commercial use depends on the terms of the access channel used to generate audio. Users should check output rights before publishing.
Website
Visit Website
seedaudio15.org
Publisher


